Uncategorized
Exploration Versus Exploitation: The Explorer’s Dilemma
Act on what you know, or seek what you don't? Every agent that learns from its choices faces this fork.
Act on what you know, or seek what you don't? Every agent that learns from its choices faces this fork.
What is learned in one place can pay off in another.
A large model's competence need not stay large.
Inside a large trained network may hide a tiny one that could have learned the task alone.
Conventional wisdom says a model too large will overfit.
There is no algorithm that is best at everything.
High-dimensional data is rarely as vast as it looks.
To regularize a model is to lean on it, gently, in a chosen direction.
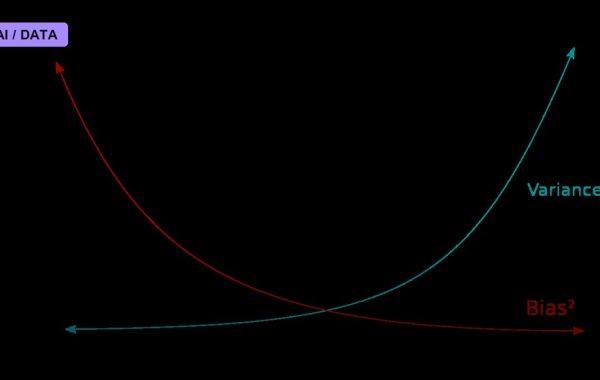
Every model that fits data faces a pull in two directions.